What is Title Search: Process, Challenges, Automation and AI Best Practices
 Oct 5th, 2026
Data enrichment can fill every blank in a record and still leave it wrong. Which fields earn their place, which sources hold up, and what catches a bad value before sales and marketing act on it? Settle all three before your next enrichment pass.
A record with no blanks looks finished, and a finished-looking record seldom gets a second look. That is where enrichment quietly goes wrong. Fill rates climb while campaigns still miss, because a wrong value is harder to spot than an empty one.
Marketers use those added details to decide who to reach and what to say. B2B teams use them to pick which accounts to work first. One stale job title can reshape both.
Whether you enrich in-house or through data enrichment services, a few early choices set the ceiling.
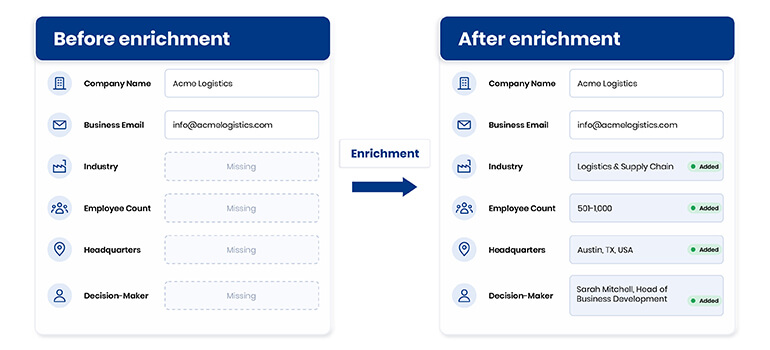
Data enrichment is the process of adding missing or updated details, such as a verified email, employee count, or decision-maker title, to records you already hold. It improves existing records rather than creating new ones.
Take a lead that arrives with only a company name and a general inquiry email. Enrichment adds its industry, employee count, headquarters, and a named decision-maker, so a sales team can act on it. Enrichment turns it into something your team can act on in three steps:
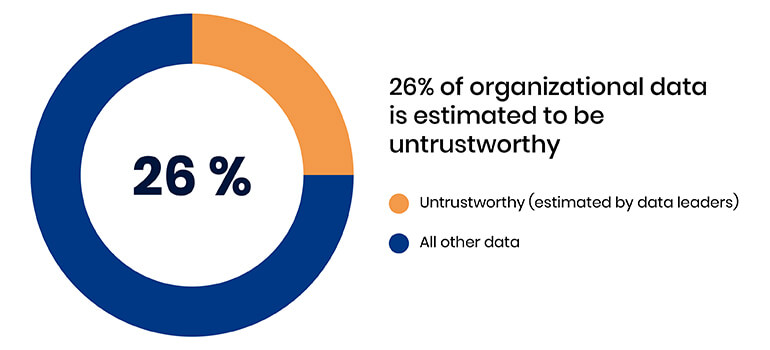
Salesforce’s State of Data and Analytics report found that data and analytics leaders estimate 26% of their organization’s data is untrustworthy. Incomplete, out-of-date, or poor-quality data was the top factor keeping companies from being data-driven.
Four problems show up most often in B2B databases.
Incomplete or missing data limits what a record can do. Common gaps include missing emails, partial phone numbers, incomplete addresses, and no named decision-maker.
Inaccurate or outdated data misleads whoever uses it. Emails bounce, phone numbers change, and contacts leave while still listed as active. Role changes, rebrands, and relocations are how B2B data decay builds up quietly.
Duplicate entries confuse reporting and outreach. The same company under two spellings, or one contact entered twice, inflates counts and skews analysis.
Inconsistent formatting makes merging harder. Mixed abbreviations, date formats, and capitalization are the usual culprits.
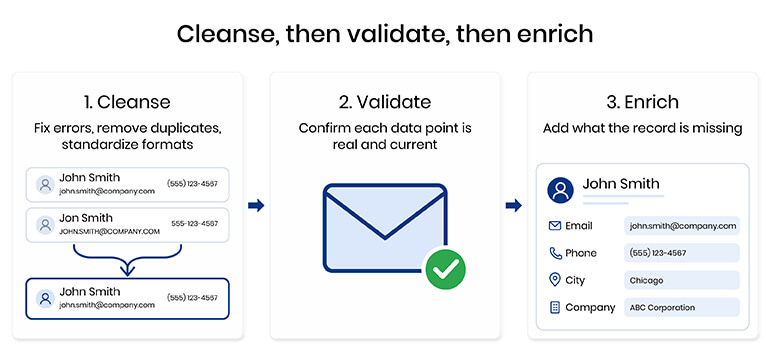
The three terms are often used interchangeably, but each does a different job. For a closer look at the first two, read our guide to data cleansing vs. enrichment.
Data cleansing fixes what is already in a record by correcting errors, removing duplicates, and standardizing formats. It adds nothing new.
Data validation checks whether a data point is real and current, such as whether an email will deliver. It often sits inside the cleansing step.
Data enrichment adds what a record lacks, such as a decision-maker’s name, a firmographic detail, or an intent signal from an external source.
On a well-managed database they run in sequence. Cleanse to remove what is wrong, validate to confirm what remains is real, then enrich to fill the gaps.
Teams with large backlogs often hand cleansing and validation to data cleansing services before enrichment begins.
Enrichment improves the record first. Business outcomes follow only when the fields you add feed a decision someone already makes.
Better data quality. Completeness and accuracy are the measurable part: how many records carry a usable email, how many titles survive a spot check, how many duplicates remain after a merge.
The stakes rise when the data itself is the product. A US advisory firm supplying financial business data to economic development organizations held records spanning more than 80 fields, verified against sources that routinely disagreed on revenue, headcount and headquarters.
Resolving those conflicts through structured verification and enrichment of the dataset improved its operational data quality, and the firm went on to win multiple bids to supply financial data though the engagement does not isolate enrichment as the only reason.
Improved lead generation. Firmographics tell you which accounts fit; decision-maker fields tell you who to approach. Together they let a team score and route leads instead of working an undifferentiated list.
The limit is practical. Appending a field your qualification process does not use changes nothing, so start from the criteria your sales team already applies.
Time and cost savings. Poor data consumes hours before anyone notices the cost. Validity’s State of CRM Data Management in 2026, a survey of 500 B2B and B2C marketing professionals across five countries, found nearly a third of teams spend six or more hours a week fixing and reconciling data.
Enrichment does not remove that work. It moves correction into a controlled process upstream, instead of leaving it to whoever opens the record at the worst moment.
Customer satisfaction. The mechanism is narrow and worth stating precisely: current contact and account data means fewer messages sent to the wrong person, fewer failed deliveries, and fewer service calls that start with a correction.
Whether that registers as higher satisfaction or better retention depends on everything else in the customer experience. Data quality removes a cause of friction; it does not create loyalty.
Regulatory compliance. Enrichment does not make a database compliant, and appending personal data increases your obligations rather than reducing them.
What it supports is the record-keeping compliance depends on: documented sources, recorded provenance for each field, and current details so access and deletion requests can be answered. Lawful basis is covered in the ethics and privacy section.
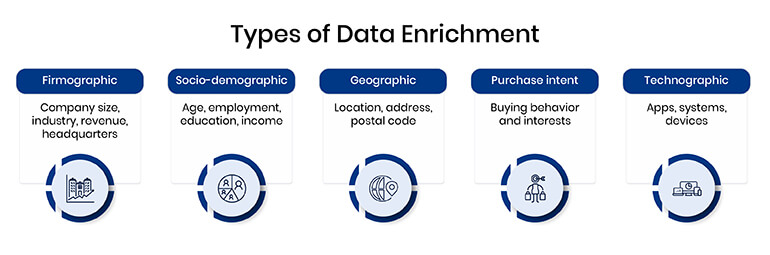
Firmographic enrichment adds company size, industry, revenue, and headquarters, so teams can segment accounts and prioritize the right ones.
Socio-demographic enrichment adds name, age, gender, employment history, education, and income to support audience analysis and targeted marketing.
Geographic enrichment adds location, address, and postal-code data for market analysis, regional targeting, and resource allocation.
Purchase intent enrichment adds signals about buying behavior and interests, gathered from public and private sources, so a business can reach a prospect at the right point in the buying journey.
Technographic enrichment adds the applications, operating systems, and devices a contact or company uses, which helps with technology-fit targeting.
Names and salutations. Names change through marriage, divorce, and personal preference. A wrong name can undermine a message before it is read.
Email addresses. Outdated emails raise bounce rates, which hurts sender reputation and deliverability for every future send.
Postal addresses. A wrong address means failed deliveries, frustrated customers, and the cost of resending.
Decision-maker details. Writing to the wrong person wastes sales time and weakens later outreach. Cross-check professional profiles, and ask your sales team, who often notice a role change first.
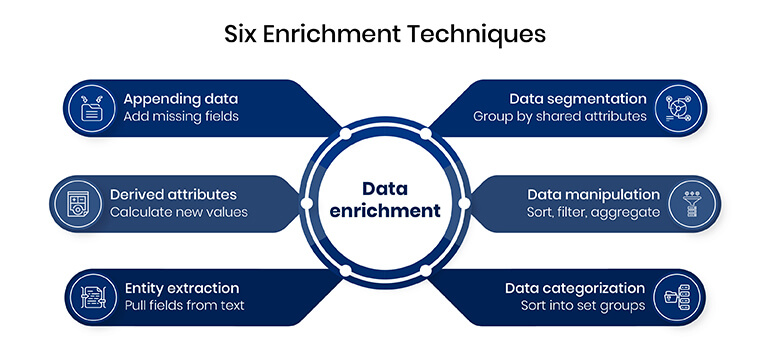
Six techniques cover most programs. Three add information a record did not hold. Three organize what you already have, necessary work, but enrichment only under specific conditions, noted below.
Data appending fills missing fields from external sources: a verified email, a current title, a named decision-maker, an industry code.
Volume is what makes it hard. Keeping a 50-million-record B2B database current means running the work continuously, which is why one California-based aggregator uses scheduled bots to append missing contact-level and firmographic fields across existing records while roughly 150,000 new company profiles are added each month.
Appending is also where wrong data enters fastest, so each appended value needs a confidence threshold and a validation step before it reaches the live database.
Derived attributes calculate new values from fields the record already holds total contract value from individual orders, headcount growth between two reporting dates, months since last activity.
No external source is involved, so accuracy inherits directly from the underlying fields. A derived attribute built on a stale revenue figure is a stale attribute that looks freshly calculated.
Entity extraction uses natural language processing to pull organizations, people, locations and dates out of unstructured text, filings, news coverage, support notes, web pages and write them into structured fields.
It is the only practical way to enrich from text at scale, and it carries model error. Treat extracted values as candidates to validate, not as confirmed fields.
Data segmentation splits a dataset into groups sharing attributes: region, account tier, industry, buying stage.
It qualifies as enrichment only when the resulting segment or score is written back to the record as a field others can query. Run as a one-off analysis, it leaves the database exactly as it was.
Data manipulation covers sorting, filtering, aggregating and standardizing, normalizing country names, converting mixed currencies to a single unit, aligning date formats.
This is preparation rather than enrichment. It adds no information, but skip it and enriched fields from different sources will not compare.
Data categorization assigns records to a defined taxonomy, such as an industry code or a product class.
It becomes enrichment when the assigned code is a new attribute derived from a recognized classification standard, applied by a documented rule. A label applied ad hoc by whoever opened the record is not.
Source accuracy. Providers differ in coverage, refresh frequency and error rate, and accuracy drifts between contract renewals as a provider’s own sources change.
Test before you commit: run a provider against a few hundred records you can independently confirm, and compare match rate and accuracy separately. Then keep validating incoming values rather than trusting them on arrival.
Record matching and integration. Sources rarely share an identifier, so records are matched on company name, domain or address, all of which vary in spelling, legal suffix and format.
A missed match leaves a blank, which is visible. A wrong match writes a correct value into the wrong record, which is not. Set a confidence threshold and route everything below it to human review instead of forcing a decision.
Scalability. Manual review is the first thing volume breaks. Automation absorbs well-defined matches, but exception queues, confidence thresholds and sampling have to scale with it.
The failure mode is quiet: throughput rises, review coverage falls, and nobody notices until a campaign fails.
Data relevance. Fields that feed no decision still cost acquisition, storage and review time, and personal data adds privacy exposure on top.
Tie each enriched field to a decision your team makes, and retire fields with nothing queries after a full cycle.
Quality after enrichment. Enrichment creates its own defects. Merging introduces duplicates, partial matches leave half-populated records, and errors inherited from a source arrive looking authoritative.
The fix is a separate stage rather than more care during the pass. A France-based aggregator maintaining 14.5 million hospitality records across 60 countries runs de-duplication and re-validation as a distinct audit step after enrichment and before the data is delivered.
Privacy and regulatory exposure constrains all five of these. The ethics and privacy section below covers lawful basis and consent.
Enrichment is only as good as what it adds. Five checks cover most of it, whether the work is yours or a vendor’s.
How current is the source? A source refreshed quarterly lags one updated continuously. Ask how often the underlying data refreshes, not how often your job runs.
What is the real match rate? High accuracy on a small matched fraction leaves most of your database untouched. Ask for both numbers, and calculate accuracy on records you submitted rather than records they matched.
Can you cross-verify it? Check a sample of decision-maker titles against two independent sources, such as a professional network and the company’s own site.
What happens when sources disagree? Decide which source wins for which field before the run, and write it down, so results stay consistent between cycles.
What did the pass create? Re-check a sample for new duplicates and half-populated records after enrichment, not only before it.
A before-and-after audit of a few hundred records surfaces most of these problems without special tooling.
Enrichment is only as good as what it adds, so check it before you trust it. Three questions cover the basics for any enrichment process, yours or a vendor’s.
How current is the source? A source refreshed quarterly lags one updated continuously. Ask how often the underlying data refreshes, not just how often your enrichment runs.
What is the real match rate?A process that claims high accuracy but enriches only a fraction of submitted records leaves most of your data untouched. Match rate and accuracy are different measures.
Can you cross-verify it? A single source carries its own errors. Check a decision-maker’s title against two independent sources, such as a professional network and the company website.
A before-and-after audit of a sample of records will surface many problems without special tooling.
Three kinds of tooling cover most needs, and most programs combine them.
Enterprise data quality platforms handle profiling, standardization and governance across a whole data estate. They suit organizations where enrichment is one part of a broader data management mandate rather than a standalone job.
Contact and company data providers supply the external records themselves, through an API or a CRM integration. Coverage varies sharply by region and company size, so evaluate them against your own records rather than published match rates.
Human-assisted services handle what automation cannot: privately held companies, ambiguous matches, and fields that need direct verification. They are the usual answer when coverage matters more than throughput.
Build or buy depends on your sources, volume, budget and compliance requirements, not on tool quality in the abstract.
| Criterion | Custom build | Commercial tool |
|---|---|---|
| Data Coverage | Limited to sources you can access and maintain | Vendor’s coverage, which varies by region and segment |
| Integration | Designed around your stack | Connectors for common platforms; custom work beyond them |
| Scalability | Scales with the engineering you fund | Scales commercially, often priced per record |
| Accuracy controls | Full control of matching logic and thresholds | Vendor logic, usually with limited tuning |
| Privacy and compliance | You own lawful basis, provenance and retention | Vendor terms govern source provenance; verify them |
| Maintenance | Internal resource, ongoing | Vendor-maintained, often under an SLA |
| Total cost | Lower licence cost, higher engineering and upkeep | Predictable subscription, rising with volume |
A mid-sized aggregator with stable, well-defined needs usually does better with a commercial tool and a faster rollout. Unusual sources or a need to control matching logic point toward a custom build or an outsourced partner.
Automation handles well-defined work reliably. It matches records against large external datasets, standardizes inconsistent formats, and flags likely duplicates far faster than manual review.
It fails in predictable places. Ambiguous matches are resolved confidently and wrongly. Stale source data is appended as though current. Bias in a source passes through unexamined.
That is the argument for putting the accuracy checks above inside the pipeline, and for routing low-confidence matches to a person rather than to a threshold.
Enriching a record as it enters the system is now standard in CRM and marketing platforms. It shortens the wait for usable data, but compresses the time available to verify it.
The checks still have to happen, either inline, or on a sample immediately afterward.
Privacy and consent. Have a lawful basis for collecting and using personal data, such as consent, and give individuals transparency and control. Depending on where your contacts live, that can mean meeting GDPR and CCPA at the same time.
Data security. Protect enriched data with encryption, access controls, authentication, and regular security assessments.
Fairness. Biased or unrepresentative sources can produce unfair outcomes. Diverse sources and periodic bias reviews help guard against this.
Transparency and accountability. Document where each data point came from and how it changed, and assign clear ownership for enrichment work.
Worker welfare. People do the manual review behind much enrichment. Fair pay, safe conditions, and compliance with labor rules are part of doing it responsibly.
Gartner found that 63% of organizations either lack or are unsure they have the right data management practices for AI. It predicted that through 2026, organizations would abandon 60% of AI projects unsupported by AI-ready data.
Complete, current records are one practical piece of that readiness. Automation already handles well-defined jobs. It matches records across large external datasets, standardizes inconsistent formats, and flags likely duplicates faster than manual review.
Humans still matter in three places. They resolve ambiguous matches, judge whether new data fits the business goal, and catch source bias an algorithm cannot see.
Real-time enrichment, where a record is enriched as it enters a system, is becoming common in CRM and marketing platforms. It shortens the wait for usable data but does not replace the accuracy checks above.
Every paragraph is under 40 words. The ethics section has no links, and the Future section has one external link.
Outsourcing fits in three situations. Volume has outgrown what your team can process without delay. The work needs research skills and tooling not worth building in-house. Or an aggregator needs enrichment running continuously rather than as a periodic project.
HitechBPO’s data enrichment services support aggregators, sales and marketing teams, and business intelligence functions that need accurate, enriched data without building that capability themselves.
Not sure yet? Start with these signs you need B2B data enrichment.
Data enrichment turns decaying, incomplete records into accurate, usable data. It works best with reliable sources, regular validation, and a clear view of which fields matter to your business.
Start by auditing a sample of your records for blanks, bounces, and duplicates. That shows how big the gap is before you choose an approach.
If you are weighing in-house against outsourced enrichment, HitechBPO’s team can walk you through what each would look like for your data.
What’s next? Message us a brief description of your project.
Our experts will review and get back to you within one business day with free consultation for successful implementation.
Disclaimer:
HitechDigital Solutions LLP and Hitech BPO will never ask for money or commission to offer jobs or projects. In the event you are contacted by any person with job offer in our companies, please reach out to us at info@hitechbpo.com