How Chain of Title Works – Tracing Property Ownership Through County Records
 Aug 24th, 2026
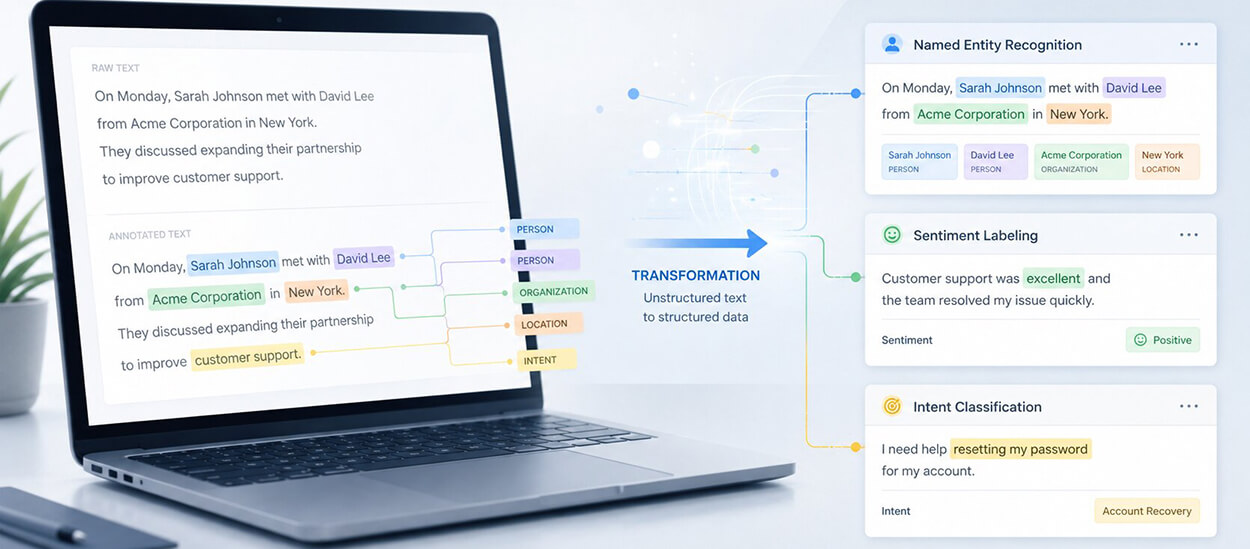
Text annotation is the process of marking up written text with labels software can learn from, such as tagging a company name or sorting a support ticket into a category. This guide covers the main types, how a project runs, the tools involved, worked examples, and how to judge label quality.
Table of Contents
Somebody has asked you to get training data ready, or a vendor has quoted for annotation work. Either way, you are trying to work out what you are actually dealing with.
Almost everything that follows comes down to two questions. What am I paying people to do, and how will I know whether they did it well?
Teams who reach the point of comparing text annotation services tend to arrive with exactly those two questions and very little else.
Both have clear answers. This page sets them out in plain language, with nothing assumed.
Text annotation is the process of adding labels to written text so that software can learn from it.
A computer does not know that “Acme Logistics” is a company. It sees a string of characters. Somebody has to point at those two words and say, this is an organization.
Do that once and nothing happens. Do it across ten thousand sentences and a pattern emerges that a machine learning model can pick up. After training, the model starts recognising company names in text it has never seen.
That is the whole idea. Humans teach by example, at scale.
A plain example
Take this sentence.
Acme Logistics filed a claim on March 14.
An annotator marks two things. Acme Logistics gets the tag ORG, short for organization. March 14 gets the tag DATE.
The sentence itself does not change. The labels sit alongside it in a data file, recording which words were tagged and what they were tagged as.
Thousands of examples like this teach the software the shape of a company name and the shape of a date, without anyone writing a rule for either.
The labeled data is treated as correct by definition. The software does not question it. It learns whatever the labels say.
That is worth understanding early. Wrong labels produce a system that confidently learns the wrong thing and never signals that anything is off.
Annotation is not proofreading and it is not analysis. It is the deliberate construction of the answer key the system will study from.
| Comparison point | Text annotation | Text labeling |
|---|---|---|
| How the term is used | The broader activity, covering tagged words, categories, links between items, and extra notes | The narrower act of assigning a category to a piece of text |
| Typical output | Marked word positions, entity types, relationship links, document categories | Class labels on documents, sentences, or individual words |
| Who tends to say it | Researchers, annotation vendors, tool documentation | Applied machine learning teams, dataset documentation |
| Does the difference affect a project | No | No |
The two terms are used interchangeably across research and industry. Anyone drawing a hard line between them is applying a personal convention rather than a standard.
What matters instead is the label schema, meaning the list of labels allowed and the rules for applying them.
Two annotators working from clear rules produce consistent data. Two annotators guessing produce a mess, whatever the activity is called.
This is the part most people get backwards, so it is worth spending a minute on.
The common assumption is that the choice of model drives accuracy. In practice, label quality usually drives more of it, and it is the cheaper of the two to fix.
The evidence is public. Researchers checking ten widely used machine learning test sets found an average of at least 3.3 percent of labels were simply wrong.
That sounds small. It was large enough to change which model appeared to be the best, meaning professionals were picking systems based on labeling mistakes rather than real performance.
Text datasets are no better. A careful recheck of a well known dataset for recognising names and organizations found errors in around 5.38 percent of test sentences.
Set those numbers against a typical situation. Two systems differ by one percent in accuracy, measured on a test set where five percent of the answers are wrong. The comparison tells nobody anything.
There is a second problem. Labeling mistakes stay hidden for a long time.
Researchers who interviewed 53 AI practitioners found that data problems resurfaced later as apparent model failures in 92 percent of cases.
Weeks then go into adjusting the software when the fault was in the data all along. This is the most common way these projects lose budget.
It shows up in business results too. McKinsey reports that 51 percent of organizations using AI have hit at least one negative consequence, with inaccuracy the most common one.
Model accuracy improves for a lower total cost than architecture work delivers. Cleaning a noisy training set frequently beats swapping in a larger model.
Evaluation becomes trustworthy. A clean test set tells you whether a change helped, which is impossible when five percent of your labels are wrong.
Debugging time drops. An error breakdown by class points at the fix, instead of sending the team through another round of hyperparameter tuning.
Model behaviour becomes explainable to auditors and business stakeholders, because every decision boundary traces back to a documented labeling rule.
Datasets stay reusable. A versioned schema with adjudication history can be extended for a new model in months rather than re labeled from scratch.
Bias becomes visible and addressable. Annotator level labels expose where judgments split by reviewer, which a collapsed majority vote hides.
Most projects follow the same ten steps, whoever is running them.
Two of these get skipped more than any others.
Step six is the pilot, and it goes first when a deadline is close. Three hundred items exposes problems that would otherwise be repeated across fifty thousand.
Step ten is the quality report. Without it there is a pile of labels and no way of knowing which parts to trust.
Guidelines are the rulebook annotators follow. Weak guidelines are the most common cause of a failed dataset.
Compare these two instructions.
“Label the company name.”
“Label the legal entity name. Exclude the word the. Exclude Ltd, Inc, and similar endings. If a division is named, label the division separately.”
The first produces five different interpretations. The second produces agreement. That difference is worth more than any tool you could buy.
Good guidelines include worked examples of the awkward cases, not just the easy ones. The easy cases were never the problem.
There are several distinct types. Most projects use two or three together, not all of them.
| Type of annotation | What gets marked | What it is used for |
|---|---|---|
| Entity annotation | Names of people, companies, places, products, dates, amounts | Pulling structured facts out of documents, search |
| Sentiment annotation | Whether text is positive, negative, or neutral | Review analysis, brand monitoring, customer feedback |
| Text classification | The category a whole document or message belongs to | Ticket routing, content sorting, moderation |
| Intent annotation | What the writer is trying to do | Chatbots, virtual assistants, call centre automation |
| Semantic annotation | Concepts and their meaning, linked to a reference list | Smarter search, question answering, recommendations |
| Linguistic annotation | Grammar, word types, sentence structure | Translation, parsing, research corpora |
| Coreference | Which words refer to the same thing across a document | Summarising, contract review, long document analysis |
| Entity linking | Which specific real world thing a name refers to | Telling two companies with similar names apart |
| Relationship annotation | How two labeled things are connected | Building knowledge graphs, extracting facts |
Annotators mark spans that name something specific and assign a type such as person, organization, location, product, date, or monetary value.
Boundary rules cause most of the disagreement. Whether “the Bank of England” includes the article, and whether a job title attaches to the person span, has to be settled in the guidelines.
Pretrained transformer models cut how much entity data you need to label from scratch. Our walkthrough of BERT for entity annotation covers how that changes project sizing.
Sentiment labels capture polarity, usually positive, negative, or neutral, and sometimes a graded scale or a defined emotion set.
Aspect level sentiment is more useful for product and CX teams. One review can praise delivery speed and criticize build quality in a single sentence, and a document level label discards both signals.
Sarcasm deserves its own flag rather than a forced polarity value. Forcing it teaches the model that surface negativity and intended negativity are the same thing.
Classification assigns a whole document, ticket, or message to one or more predefined classes. Support triage, content categorization, and compliance screening are the common commercial uses.
The taxonomy does most of the work here. Overlapping classes and a missing “none of these” option generate inconsistency that annotator training cannot fix.
Intent labels describe what the writer wants, such as cancel_subscription or report_outage. Conversational AI systems train on these to select a response path.
Intent sets degrade as they grow. Adding an intent that overlaps an existing one quietly corrupts the classes around it, so each addition needs a re-labeling pass on affected examples.
Semantic annotation tags concepts, senses, and topics, then links them to formal descriptions in a knowledge graph. It converts unstructured content into something a retrieval system can filter.
This is what turns “Apple” in a market report into a specific company identifier rather than an ambiguous string.
Linguistic annotation covers parts of speech, dependency structure, morphology, and discourse features. It is standard in academic corpora and machine translation pipelines.
Commercial NLP projects need it less often than they assume. Pretrained models already encode much of it, so annotate it only when a downstream component consumes it directly.
Coreference annotation groups mentions across a document that refer to the same real world entity, including pronouns, abbreviations, and later references by role.
It matters most where meaning is assembled across long documents. Contract review and clinical notes both break when “the borrower” and a named party are treated as separate entities.
Entity annotation marks a span and assigns it a type. Entity linking maps that span to a specific record in a knowledge base such as Wikidata or an internal master data table.
Entity annotation answers what kind of thing this is. Entity linking answers which specific thing it is. Search relevance and knowledge graph projects usually need both layers.
Relationship annotation records how two labeled entities connect, such as an executive employed_by an organization or a payment issued_to a party.
Relation labels sit on top of the entity layer, so entity errors multiply here. Audit the entity before relation work starts.
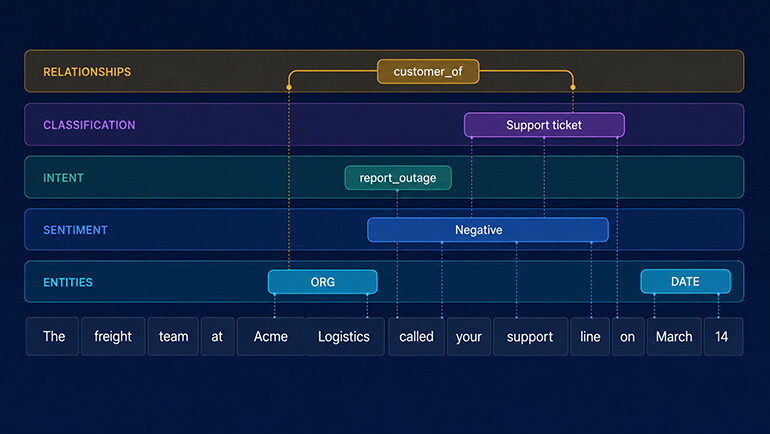
Here is how the types fit together in practice. A single line of text.
The freight team at Acme Logistics called your support line on March 14 because the tracking dashboard had been down for two days, and they were not happy about it.
Five kinds of information from one sentence. Labeling all five in a single pass costs far less than running five separate projects.
Context changes the answer. In “Chicago won game one,” Chicago is a sports team, not a city. An annotator without that context tags it as a location and teaches the model something false.
Tone can invert. “Well, that was worth the wait” is negative in almost every real context, despite containing no negative words.
Boundaries need a decision. In “the Bank of England governor,” is the label the organization, the job role, or both as overlapping tags? Any answer works if everyone uses it.
Collect examples like these from your own data before writing guidelines. They are the cases that decide whether a dataset holds together.
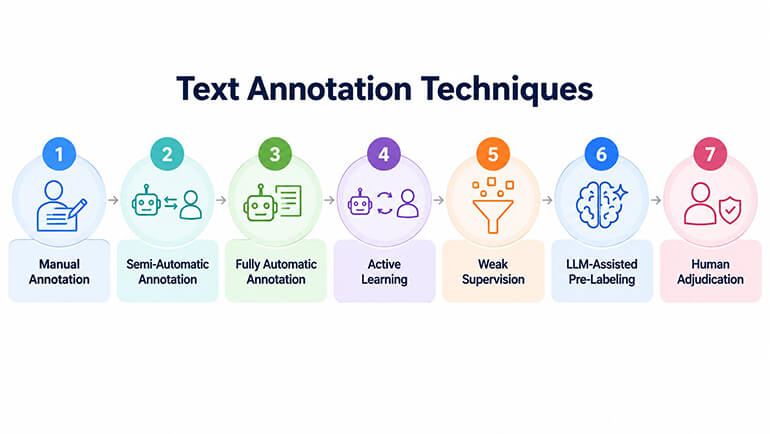
Manual annotation from scratch gives the highest quality on new or specialized label sets. It is the slowest option and the correct one when no usable model exists yet.
Semi automatic annotation places a model between the corpus and the annotator. The model proposes, the human disposes, and throughput rises sharply.
The catch with pre labeling is automation bias. Annotators accept plausible wrong predictions more readily than they produce wrong labels themselves, so audit rates should rise rather than fall.
Fully automatic annotation applies a model or ruleset without human review. It suits high volume, low ambiguity labels such as language identification or well defined document types.
Active learning routes the items a model is least confident about to human annotators. It concentrates effort at the decision boundary and repays its setup on corpora above roughly a hundred thousand items.
Weak supervision generates noisy labels at volume from rules, patterns, and dictionaries, then denoises them statistically. It works for regulated vocabularies and fails for subjective judgments.
LLM assisted pre labeling has largely replaced rule based bootstrapping. The important caveat is that LLM errors are correlated, so a second model tends to confirm the first model’s mistakes rather than catch them.
Human adjudication stays the control in all of these. Our deeper breakdown of text annotation techniques covers throughput and tooling per approach.
Annotation tools are simply interfaces that make marking text fast and consistent. They store the labels in a structured file your data team can use.
Open source options cost nothing to license but need someone to host and maintain them.
Label Studio is the most flexible and handles text, images, and audio. doccano is lighter and good for classification and simple tagging. INCEpTION suits meaning and linking work, and brat is still used in research.
Commercial platforms add team management, quality dashboards, audit trails, and security controls. Prodigy, Labelbox, and Snorkel are common choices.
Ready made language APIs from AWS, Google, Microsoft, and IBM will tag entities and sentiment straight away. They are most useful for generating a first draft that people then correct, and as a benchmark your own model should beat.
Do not overthink this decision at the start. A clear label schema in a basic tool beats a vague one in an expensive platform. Tooling is easy to change later. A confused dataset is not.
| Factor | Human annotation | Automated annotation |
|---|---|---|
| Accuracy on nuance | Strong on ambiguity, sarcasm, and domain context | Degrades outside the training distribution |
| Scalability | Limited by team size and training time | Effectively unlimited once configured |
| Cost | Higher per item, driven by task complexity | Low marginal cost, higher setup cost |
| Context understanding | Handles implication and world knowledge | Pattern based, misses implied meaning |
| Consistency | Varies between people and across weeks | Perfectly consistent, including when wrong |
| Speed | Items per hour | Items per second |
| Best fit | New taxonomies, subjective or specialized data | Large volumes of routine, well defined labels |
| Oversight needed | Peer review and adjudication | Mandatory human audit of a sampled subset |
Automated annotation fails in a way that matters. It is confidently and uniformly wrong on cases outside its training data, which makes its errors harder to spot than human errors.
Human in the loop annotation resolves this by letting the model handle the routine majority and sending the hard remainder to people. Deciding what counts as hard is the part worth designing carefully.
Routing rules usually combine model confidence, class rarity, and document complexity. Low confidence predictions, rare classes, and long documents justify human review even when overall accuracy looks acceptable.
Corrections then become training data. Each adjudicated batch improves the pre labeling model, which shrinks the human share of the next batch.
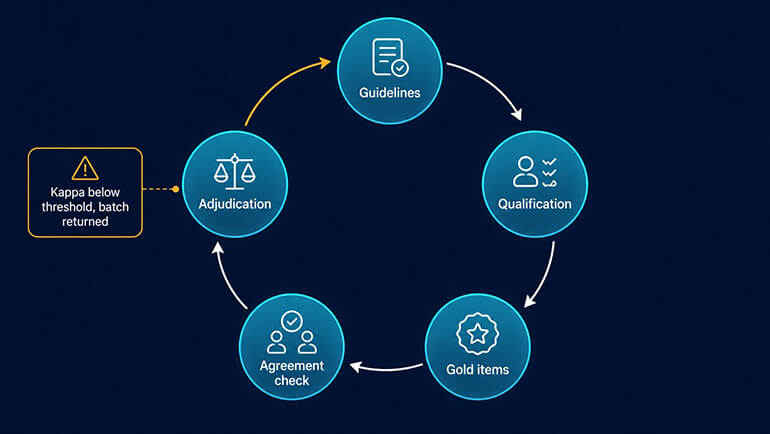
Most annotation quality claims are adjectives. The ones worth trusting are numbers, produced by a method the vendor will describe on request.
Write guidelines as decision rules rather than descriptions. “Label the company name” produces inconsistency. “Label the legal entity name, exclude the article, exclude the legal suffix” produces agreement.
Qualify annotators before production. A short test on items with known answers separates people who need retraining from people who are ready.
Seed gold items with known answers into every batch. They measure drift continuously instead of at project end, when re labeling is at its most expensive.
Double annotate a sample rather than the whole corpus. A second pass on ten to twenty percent gives a defensible agreement figure without doubling project cost.
Report a chance corrected agreement coefficient rather than raw percentage agreement, which flatters skewed label distributions badly.
Treat disagreement as diagnostic rather than as failure. On subjective tasks, keep annotator level labels instead of collapsing everything to a majority vote, because the variance is signal.
Audit by error type rather than error rate. Knowing that most errors are boundary errors on one entity class tells you what to fix. Knowing accuracy is 96 percent does not.
Ambiguous spans come from undefined boundaries and nesting rules. Fix them with worked examples for every edge case in the guidelines.
Subjectivity and sarcasm break polarity scales. Add separate flags instead of forcing a value that misrepresents the text.
Context dependency causes wrong labels when annotators see isolated snippets. Give them the full document view.
Domain terminology defeats generalist annotators. Use domain trained professional working from a client approved glossary.
Label drift creeps into long projects as interpretation shifts. Recurring gold items in every batch catch it within days rather than months.
Taxonomy changes mid project are expensive. Version the schema and scope a re labeling pass on affected classes only.
Multilingual corpora need native speakers per language. Translating first and annotating second discards exactly the nuance you are paying for.
Volume against fixed deadlines is best solved by model pre labeling with human review concentrated on the hard subset, not by adding annotators to every item.
Data sensitivity requires controlled environments, access logging, and role based permissions rather than a generic compliance claim.
Healthcare. Clinical notes and medical literature are labelled for conditions, medications, dosages, and outcomes. That work sits behind medical coding, finding suitable patients for a trial, and flagging patients at risk of readmission from what a doctor typed into a record.
Banking and insurance. Filings, call transcripts, and customer messages are labelled for names, amounts, and risk signals. It powers fraud checks, compliance screening, and the banking assistants that answer questions about a transaction or an upcoming bill. Bank of America’s Erica is the best known example of the latter.
Retail and ecommerce. Reviews, search queries, and product descriptions are labelled for tone, product attributes, and category. A retailer can then see that complaints about one product line are all about packaging rather than the product itself. Much of that work feeds sentiment and intent analysis reporting.
Customer support. Tickets and chat transcripts are labelled by intent and issue type. That drives automatic routing, spots the five issues generating half the ticket volume, and tracks whether sentiment improves after a fix ships.
Human resources. Applications, CVs, and staff survey responses are labelled by skill, role, and theme. HR professionals use it to shortlist consistently and to see which concerns recur in free-text feedback, which a rating scale never captures.
Legal and real estate. Contracts and property records are labelled for parties, dates, obligations, and clause types, so a review that took hours of reading becomes a structured summary.
Media and publishing. Articles are labelled by topic, named entities, and stance, which powers article recommendations and makes a decades-old archive searchable.
Generative AI programs annotate instruction data, preference rankings, safety categories, and evaluation sets. These are annotation projects with the same guideline discipline, and they underpin LLM training data work.
Text annotation creates labeled training data. Text analytics extracts insight from text, usually with models trained on annotated data.
Annotation is an input activity and analytics is an output activity. The quality ceiling of the second is set by the first.
Mature programs run them as a loop. Analytics output shows which categories the model handles badly, those examples return for annotation, and the retrained model improves the analytics.
Teams already running text analytics services have the clearest view of which labels underperform, because they watch the failures surface in production reporting.
A Germany based construction technology company needed news articles classified by project size, phase, location, and architect to feed a construction leads platform used by enterprise clients.
Auto classification handled the bulk of the volume. Around 20 percent of articles were too complex for it and went to trained human annotators, with a two step quality check on every batch.
More than 10,000 construction articles were classified and validated on a 24 hour turnaround cycle. Search relevance improved and project cost fell by half, detailed in the text classification case study.
The transferable lesson is the split rather than the tooling. Identifying which subset genuinely needs human judgment is what makes hybrid annotation cheaper than either extreme.
The price per item is the least useful number in a quote. Four other things move the total far more.
How much is marked per item. One category on a sentence is a fraction of the work of nine tagged names and three relationships in the same sentence.
How many labels exist. Every extra category slows decisions and lowers agreement. Beyond roughly thirty, you need a structured hierarchy.
How specialist the text is. Clinical or legal material needs trained annotators, which means a ramp up period before full speed.
How much checking is included. One pass, a checked sample, or full double labeling with a reviewer are three different prices for three different reliability levels.
And the cost nobody quotes. Changing the label list when the project is 60 percent done can cost more than the original pass. This is the entire argument for running a pilot first.
Handle it internally when the dataset is small, the subject is unique to your business, and someone has time to write and maintain the rules.
Bring in help when volume is large and the deadline is fixed, when the text spans several languages, or when new data arrives every week and needs steady throughput.
One thing worth saying plainly. Data scientists labeling their own data is the most expensive arrangement available, and it is very common.
Ask how quality is measured, not whether it is high. A real answer mentions agreement scores, gold item pass rates, and a breakdown of errors by category.
Ask who writes the guidelines and how updates reach the team mid project.
Ask about annotator training and retention in your subject area. A team rebuilt every quarter cannot hold specialist rules steady.
Check how your data is stored and who can see it, especially if the text contains personal information.
Confirm the delivery format matches what your engineers need, including how corrections are handled across versions.
Shortlist against your own criteria before taking a demo. Our roundup of data annotation companies sets out how the main providers differ on domain coverage and QA depth.
If your work spans images or video as well as text, the wider data annotation services practice covers those in the same programme.
A longer walkthrough with workflow templates sits in our resource on text annotation to boost AI and ML training.
Text annotation sets the accuracy ceiling of every supervised NLP system you build. Model selection moves performance by a few points.
Label quality moves it by considerably more, and it distorts evaluation as well, which is worse because that hides the problem.
The work separating a usable dataset from an unusable one is unglamorous. Decision rules instead of descriptions, gold items in every batch, measured agreement, and adjudication that actually updates the guidelines.
Send us your label schema and a sample of your text. Our team will review the taxonomy, flag the ambiguities most likely to cause annotator disagreement, and scope an annotation and QA workflow around your accuracy target.
What’s next? Message us a brief description of your project.
Our experts will review and get back to you within one business day with free consultation for successful implementation.
Disclaimer:
HitechDigital Solutions LLP and Hitech BPO will never ask for money or commission to offer jobs or projects. In the event you are contacted by any person with job offer in our companies, please reach out to us at info@hitechbpo.com