How Chain of Title Works – Tracing Property Ownership Through County Records
 Aug 24th, 2026
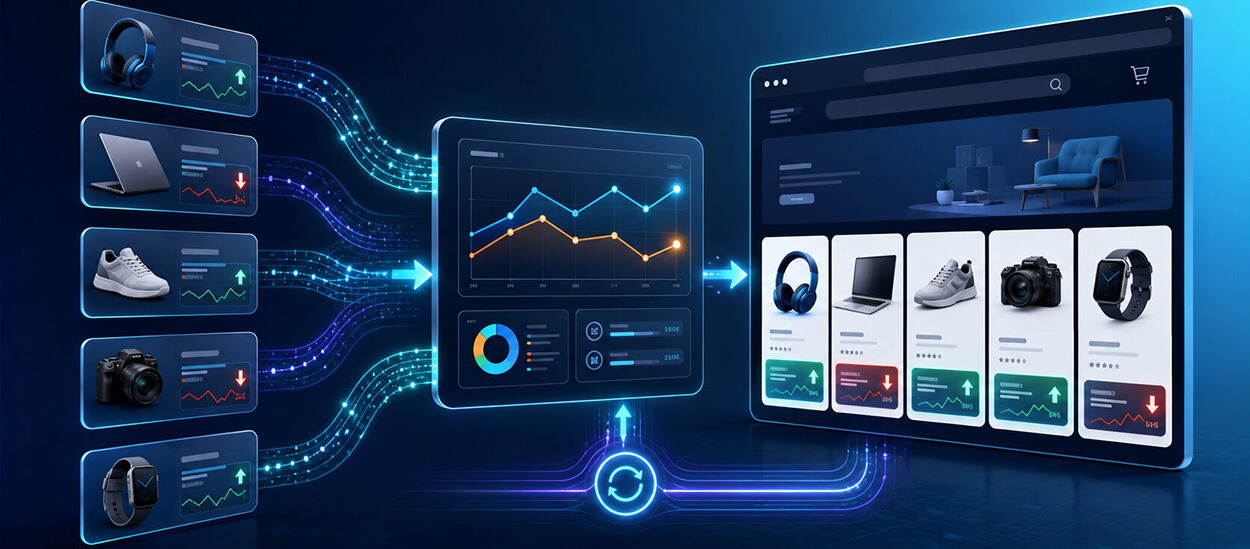
Dynamic pricing works only when the competitor data behind it is accurate. This guide covers landed price calculation, product matching, repricing rules, data quality gates, API versus scraping collection, and the 2026 pricing rules eCommerce teams now have to price around.
Table of Contents
Most eCommerce pricing decisions still run on stale information. A merchandiser checks a few competitors on Monday, sets prices for the week, and hopes the market holds still.
It does not. By Wednesday a price can be too high to convert or too low to protect margin, and nobody finds out until the sales report runs.
Automated repricing closes that gap, but only when the data layer underneath is sound. That layer comes from competitor prices collected on a schedule, through official APIs where they exist and scraping where they do not.
Retailers who would rather not run that infrastructure hand it to managed web scraping services instead. Either way, the same four principles decide whether the pricing engine can be trusted.
Collect shipping, stock and promotion status alongside price. Put most of your engineering effort into product matching.
Gate the feed with validation rules before it touches a live price. Keep the rules simple enough that a merchandiser can explain any change to a director.
Dynamic pricing has a reputation problem and most of it is self-inflicted. Teams deploy a pricing engine that reacts to scraped headline prices without accounting for shipping, stock status or promotion timing, then spend months chasing noise. Prices whipsaw against a competitor’s three-day coupon. Rules undercut a rival who is actually out of stock and posed no threat at all. That looks like automation and behaves like guesswork, and it is a data quality problem wearing a pricing strategy label.
The upside when it is built properly is real but moderate. McKinsey benchmarks dynamic pricing at roughly 2 to 5 percent sales growth and 5 to 10 percent margin improvement in tested pilot categories.
The market is scaling regardless of whether individual implementations are sound. Industry estimates put the global dynamic pricing software market at roughly $3.49 billion in 2025, growing toward $6.9 billion by 2030 at close to 14.6% annual growth, according to the business research company ‘s 2026 market report. More retailers are adopting these systems well before most have solved the underlying data problem.
Amazon offers a useful reference point for how fast the leaders actually move: it reportedly pushes around 2.5 million price changes a day, close to one update every ten minutes on a given listing, according to bigcommerce’s 2026 industry analysis. Weekly manual checks aren’t a slower version of that. They’re a different category of process entirely.
Retailers usually start by asking for competitor prices. That one field is not enough to price against, and every field missing from the record creates a class of pricing error that surfaces weeks later in a margin report.
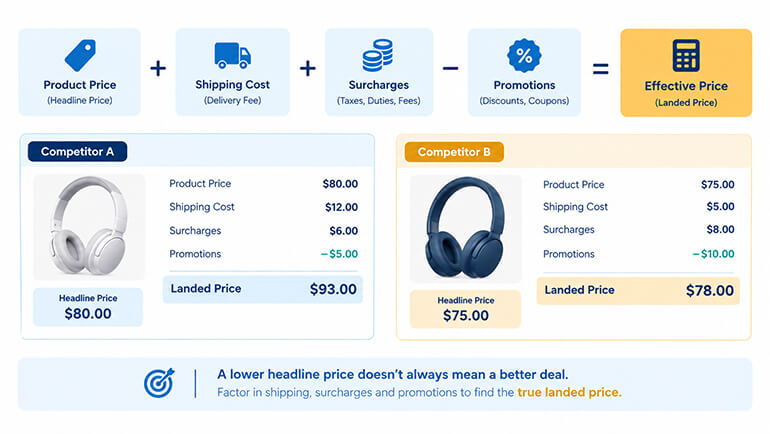
Direct answer: the number that matters is landed price, not headline price.
Effective Price = Product Price + Shipping + Surcharges – Promotions
A cheaper listing carrying a shipping fee can land more expensive than a pricier one with free delivery. Repricing off headline price alone produces a systematically wrong competitive read, and it does so quietly, because every individual capture looks correct.
| Scraped data point | Strategic pricing signal | Impact on pricing rules |
|---|---|---|
| Base or headline price | Nominal competitive position | Baseline input, never the final comparison |
| Shipping cost and free-shipping thresholds | True landed cost | Corrects false price-match triggers |
| Real-time stock status | Supply pressure | Enables margin capture on competitor stockouts |
| Active promotions and coupons | Temporary versus permanent discounting | Prevents overreacting to short-lived deals |
| Historical price series | Volatility and seasonality | Sets how aggressively to react |
| Seller identity on marketplaces | Who you are actually competing with | Stops pricing against an unrelated reseller |
| Ratings and review volume | Demand and sentiment strength | Calibrates whether to discount or hold a premium |
| Capture timestamp, region and URL | Auditability | Makes a bad price debuggable after the fact |
Stock status is the most underused signal there. A matched competitor going out of stock is a low-risk window to hold or lift price, rather than match a discount nobody can buy.
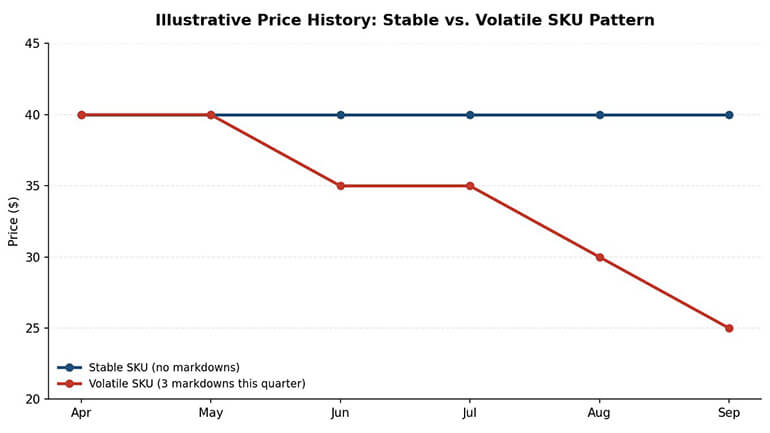
A single scraped price is a snapshot. A price series is a pattern, and the pattern is what should inform a rule.
A $39.99 price point means something quite different if it has held for six months than if it is the third markdown this quarter.
History tells you whether a discount is a permanent repositioning or a clearance that will end on its own, and how deep a rival typically goes before stopping. Without it, a rules engine treats every movement as equally significant.
Structuring that history so it is usable at catalog scale is its own exercise, covered in our guide to eCommerce data collection strategies.
None of this works if the listing you captured is not the product you sell. Matching your SKU to the right competitor listing, not a similar one or a different pack size, is where most in-house pricing projects break down.
Reliable matching layers identifiers by confidence. UPC and GTIN first, MPN with brand or model second, machine-learning fuzzy title matching last for listings with no clean identifier.
Attach a confidence score to every match. Anything below your threshold goes to human review rather than to the pricing engine.
The failure mode is not intuitive. An unmatched SKU is visible, because the feed has a gap and someone notices.
A wrongly matched SKU is invisible. The engine gets a real price for the wrong product and acts on it, sometimes for weeks. This is where eCommerce catalog management discipline beats a homegrown matching script.
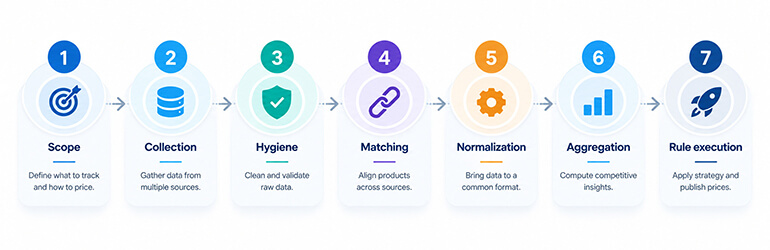
Price scraping is the automated collection of competitor product, price, stock and promotion data from retailer sites, marketplaces and APIs, normalized into a structured feed a pricing engine can act on. In production it runs as a seven-stage pipeline, and each stage has a distinct failure mode.
Teams building this the first time underestimate stages 4 and 5 by a wide margin. Our work on a fashion aggregator involved normalizing 2 million-plus SKUs from seven vendor sources, which removed up to 40 percent duplicate records. Those duplicates were not a collection failure. Collection worked fine. Normalization was doing all the work.
| Method | Data completeness | Anti-bot resilience | Maintenance overhead | Best fit |
|---|---|---|---|---|
| Price scraping bots | High, fragile to layout changes | Requires ongoing investment | High and continuous | Long-tail competitors with no API |
| RPA bots | High on authenticated portals | Not applicable | High | Supplier portals and legacy interfaces |
| In-house scripts | As high as you build it | Your team’s problem | High, and it is your roadmap time | A small, stable set of high-value sources |
| API-based scraping | High, maintained by provider | Provider absorbs most of it | Low to moderate | Most production price monitoring |
| Official vendor APIs | Limited to what the vendor exposes | Not applicable | Low | Marketplaces and partners you sell through |
Custom bots send requests, retrieve HTML and extract the fields you defined. They cover many sites in parallel on a schedule, which keeps them the default for competitors that publish nothing structured.
The cost is maintenance, and the danger is silence. A selector that stops matching after a redesign usually returns null rather than raising an error, so bad data flows into the pricing engine with no alarm. Bot fleets need field-level completeness monitoring, not uptime monitoring.
RPA drives a browser the way a person would, which makes it useful for supplier portals and legacy interfaces needing a login and a sequence of clicks.
For public price monitoring at scale it is the wrong instrument. Cost per record is high, throughput is low, and it breaks on interface changes while being harder to debug than a scraper.
Building in-house buys full control of logic, storage and integration. For ten to twenty stable, high-value sources it can be the right call.
The recurring work is not writing scrapers. It is proxy and session management, CAPTCHA handling, monitoring for silent breaks, and rebuilding matching logic whenever a competitor renames products.
Two different things get called an API here. Official or partner APIs are published by the platform, with authorized access, a versioned schema and an SLA, but coverage limited to what the platform exposes.
Commercial scraping APIs are third-party services that manage proxies, rendering, retries and parsing, returning structured records from sites publishing no API of their own.
Both remove the most fragile part of the pipeline. Neither removes matching and normalization, which stay yours wherever the raw data comes from.
The fifth option makes accuracy someone else’s contractual obligation, with a provider running collection, normalization and QA against agreed coverage, freshness and accuracy targets.
It suits retailers needing broad competitor coverage without running scraping infrastructure, and it is where most of our retail data collection services engagements begin.
Where an API is available it removes four specific problems.
APIs are versioned, with published deprecation timelines, so a change arrives as a scheduled migration rather than a silent outage. A competitor’s redesign gives a scraper no such notice.
Authorized access sidesteps the detection arms race. Cloudflare, which fronts roughly a fifth of the web, switched to blocking AI crawlers by default on new domains in July 2025. Detection has also moved past user-agent checks to TLS fingerprinting, so collection infrastructure that worked two years ago fails now.
Retailers show different prices by geography, membership tier and session history, so one capture gives one version of the truth. APIs usually accept region or currency as a parameter.
Caps on calls per minute set how many SKUs you can refresh daily, which sets how fast prices can respond. Do the arithmetic first. A 50,000 SKU catalog against six competitors at hourly refresh is 7.2 million calls a day, which no rate limit supports. Production systems run tiered refresh.
Each benefit below depends on a specific field in the feed, which is why the strategy has to be defined before the pipeline is built.
A build sequence that works, in order.
Teams needing full product attributes alongside price usually extend the same pipeline into broader data extraction services covering specifications, images and descriptions.
Clean data is the input. These are the rules worth running on it.
Median competitive matching with a capped drop. Track toward the market median rather than the single lowest listing, with a maximum decrease per cycle. The cap stops two mirror-image algorithms racing each other to zero margin.
Hard margin and MAP floors. No rule may breach a configured profit floor or a MAP commitment, however aggressive the market gets. This is the one non-negotiable rule in any automated system.
Competitor out-of-stock capitalization. Hold or lift price when a matched rival stocks out, instead of discounting against a price nobody can buy.
Velocity-based repricing. Adjust against days of inventory remaining, not only competitor behaviour. A slow mover with 200 days of cover needs a different response than a fast mover with twelve.
The business model changes the emphasis. Marketplace sellers competing for the Buy Box need seller identity in every record. Direct-to-consumer brands watch the wider resale ecosystem for MAP breaches.
B2B distributors have a harder problem, since tier breaks and rate cards rarely appear on a product page at all.
None of this removes the human. Scraper errors and genuine demand shocks slip through any rule set, so someone reviews exceptions. Large catalogs usually need the product data structured first, which is where eCommerce product data solutions sit alongside the pricing feed.
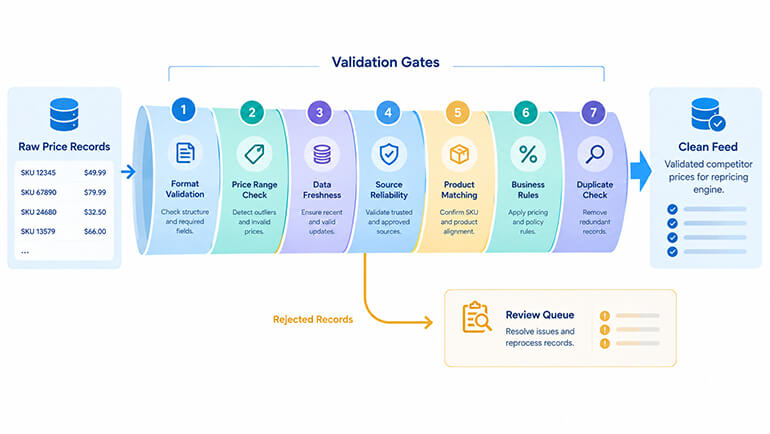
Automated repricing without validation gates is how a parsing bug becomes a pricing incident. These checks belong between the feed and the engine.
Set these thresholds with the pricing team, not the engineering team. What counts as an implausible price movement is a merchandising judgment, and merchandising owns the consequences.
Teams formalizing this for the first time may find our data collection guide useful for the surrounding process design.
This is the material change since this article was last updated, and most retailers are behind on it. The rules now separate three things that used to be discussed together: collecting public competitor data, using competitor data inside a shared algorithm, and setting individual prices from personal data.
Collecting public price data remains legally defensible in the US. The Ninth Circuit in hiQ Labs v. LinkedIn held that the Computer Fraud and Abuse Act does not reach publicly accessible data, and in Meta Platforms, Inc. v. Bright Data Ltd. (No. 3:23-cv-00077-EMC, N.D. Cal., January 23, 2024) the court found that terms governing a user’s account did not bind logged-off collection of public pages. The line across these cases is authentication: public and logged-out is defensible, behind a login you accepted terms to reach is not.
Using competitor data inside a shared pricing algorithm is now restricted in California. AB 325 amended the Cartwright Act to prohibit the use or distribution of a “common pricing algorithm,” defined as a methodology used by two or more persons that uses competitor data to recommend, align, stabilize, set or otherwise influence a price. It took effect January 1, 2026, and it applies even where the competitor data is publicly available.
Any retailer using a third-party pricing tool that pools competitor inputs across its client base should read that vendor contract again. Alston & Bird’s advisory on AB 325 sets out the definitions.
Setting individual prices from personal data now triggers disclosure duties. New York’s Algorithmic Pricing Disclosure Act requires a conspicuous notice when a price is set by an algorithm using a consumer’s personal data.
In the EU, Article 6(1)(ea) of the Consumer Rights Directive requires traders to disclose when a price has been personalized through automated decision-making, as set out in the European Parliament’s study on personalised pricing.
Dynamic pricing where every shopper sees the same current price sits outside most personalization rules, so keeping the two architecturally separate saves compliance work later.
One more rule catches European retailers running automated markdowns. The Omnibus Directive requires an advertised “was” price to be the lowest applied in the previous 30 days, so a fast-moving repricer can generate non-compliant discount claims by accident.
There is a reputational cost alongside the legal one. Gartner found that 68 percent of US consumers feel taken advantage of when brands use dynamic pricing, in an October 2024 survey of 303 US consumers.
Set against a 2 to 5 percent revenue upside, that is a real trade. None of this is legal advice, and pricing logic should be reviewed by counsel in each market where you operate.
Building scrapers in-house looks inexpensive until the maintenance bill arrives. Selectors break on redesigns, rendering changes create silent gaps, and proxy rotation becomes an infrastructure project competing with product roadmap time.
| Evaluation criteria | In-house build | Managed data partner |
|---|---|---|
| Ongoing engineering hours | Continuous, routinely underestimated | Absorbed by the provider |
| Anti-bot adaptation speed | Limited by internal bandwidth | Dedicated to the problem |
| Pipeline uptime | Self-managed, no formal guarantee | Contractually defined targets |
| Time to a working pipeline | Weeks to months of build | Materially faster to launch |
| Control over logic and storage | Complete | Shared, defined by contract |
The trade is honest in both directions. In-house keeps full control at the cost of permanent engineering attention, while a managed partner trades some control for speed to a working feed.
Two shifts are worth planning around, and they pull in opposite directions.
Collecting from the open web is getting harder. Default crawler blocking, paid crawl access and detection that fingerprints TLS handshakes rather than user agents all raise the cost of unauthenticated collection. The gap between casual scraping and production-grade collection is widening. Occasional manual checks will keep working; large-scale unattended collection increasingly needs real infrastructure or a partner who maintains it.
Structured product data is simultaneously becoming more available, because retailers now want machines to read them. AI shopping assistants compare products across merchants in seconds, and the protocols built for them expose catalog and price data deliberately.
Those include the Agentic Commerce Protocol from Stripe and OpenAI, Google’s Universal Commerce Protocol announced at NRF 2026, and Model Context Protocol servers giving agents access to live inventory and pricing.
That changes the pricing question. When an assistant compares your listing against fifteen others in under a second, price competitiveness is evaluated continuously rather than whenever a human visits.
Your own feed has to be accurate and complete or you get compared on an incomplete version of your offer. Competitor data increasingly arrives from those same surfaces, shifting the differentiator to matching speed.
Dynamic pricing succeeds or fails on the data feeding it, not on the sophistication of the rules layered on top. Solve collection, matching and landed-cost normalization first, and the pricing logic becomes simple enough to trust.
The compliance picture changed materially in 2025 and 2026. Collecting public competitor prices remains on solid ground, but feeding that data into a shared algorithm now carries obligations that did not exist when most pricing stacks were designed.
If you would rather not run the collection layer yourself, our team builds and maintains normalized competitor price feeds against agreed coverage, freshness and accuracy targets. Send us your catalog scope and competitor list for a coverage and accuracy plan.
What’s next? Message us a brief description of your project.
Our experts will review and get back to you within one business day with free consultation for successful implementation.
Disclaimer:
HitechDigital Solutions LLP and Hitech BPO will never ask for money or commission to offer jobs or projects. In the event you are contacted by any person with job offer in our companies, please reach out to us at info@hitechbpo.com